
The result first
Saudi plates are the hardest of the six GCC formats. Every plate carries the same registration twice — once in Arabic, once in Latin — and a reader that handles only one script is discarding half the evidence on every vehicle.
We read both rows. Not by converting the Latin into Arabic through a lookup table — which is what "Arabic support" usually means — but by detecting the Arabic characters on the plate, independently.
We took 106 plate images from real traffic footage our system had never seen, had a human read each one, and scored the complete plate string our API returns — digits and letters, exactly right or not at all.
- Arabic reads at parity with Latin — 89.1% on digits either way, 80.4% against 78.3% on letters, where the Arabic is genuinely read rather than converted
- Reading both rows raises the ceiling — the correct letters are present on 84.8% of frames against 78.3% from the Latin row alone, because the two scripts fail on different ones. We don't claim that as our accuracy; what we ship is the disagreement
- 8 of 8 frames read perfectly at the resolution a purpose-built ANPR camera delivers (150 px or wider across the plate) — digits and letters, no errors
- 61.9% of vehicles fully correct across the entire set; 81.0% on digits alone
And the numbers most vendors leave out. On single frames — one at a time, no multi-frame vote, median plate width just 82 pixels:
| single frame, all 106 | correct |
|---|---|
| digits only | 71.7% |
| letters only | 57.3% |
| complete plate | 50.0% |
Letters are the weaker half and we are not going to pretend otherwise. They are the thin tail of any plate corpus — the rarest letters appear a fraction as often as a common digit — and closing that gap is where our current annotation effort is going.
What "correct" means here. Our reviewer recorded each plate as the registration reads in Latin — digits plus Latin letters — so the digits/letters/complete-plate figures above are scored against the Latin row. The Arabic row is scored separately further down, against the same human reading, which is possible because Eastern Arabic numerals map one-to-one onto the digits.
How to read the units. The set is 106 frames covering 42 distinct vehicles — a tracked car yields several frames of the same plate. A real deployment votes across those frames, which is why per-vehicle accuracy (61.9%) is higher than per-frame (50.0%).
We lead with the weakest numbers deliberately. The interesting question in plate recognition is never "what is your accuracy." It is under what conditions — and an accuracy figure without its conditions attached is marketing.
Why the Arabic row is worth reading
A Saudi plate is bilingual by law — the same registration in Arabic above, Latin below. Most plate readers handle the Latin and then manufacture the Arabic by converting it through the official alphabet table. That produces a plausible Arabic string on every plate and tells you nothing, because it is a lookup, not a reading. Feed such a system a plate where the Latin row was misread and it will hand you a confident Arabic rendering of the same mistake.
We detect the Arabic characters on the plate independently. That is a data problem before it is a model problem.
Reading Arabic natively requires someone to have drawn a box around tens of thousands of individual Arabic characters, on real Gulf plates, in the conditions those plates are actually photographed in — glare, motion blur, oblique angles, night. There is no public dataset for this and no way to shortcut it: you either commission that annotation or you don't have the capability. That corpus is the single hardest part of this system to replicate, and it is the reason the Arabic numbers above exist at all.
Here is what it buys, scored against the same human reading on frames where the Arabic was genuinely read off the plate:
| Latin row | Arabic row | present in at least one row (ceiling) | |
|---|---|---|---|
| digits correct | 89.1% | 89.1% | — |
| letters correct | 78.3% | 80.4% | 84.8% |
The Arabic row is not the weaker one. It matches Latin on digits and edges ahead on letters. More importantly the two scripts fail on different frames: the correct letters are present in at least one row on 84.8%, against 78.3% for Latin alone. On digits the same holds — 71.7% from Latin, 70.8% from Arabic, 76.4% from at least one.
Be clear about what that 84.8% is. It is a ceiling, not our accuracy. Picking the right row every time would require knowing which row is right, and we don't have a rule that does that reliably — the more confident row is not dependably the correct one. So we do not claim 84.8%.
What we ship instead is the disagreement itself. On the frames where the rows conflict, we tell you they conflict, rather than silently returning one of them. A single-script reader cannot offer that at any confidence threshold, because it never had the second reading. The extra information is real; we surface it rather than pretending we can automatically resolve it.
How Arabic letters can be scored at all: Saudi plates use an official 17-letter alphabet in which each permitted Latin letter has exactly one Arabic counterpart, so a human's Latin reading can be expressed as Arabic ground truth without asking the model anything. The trap is circularity — if our system converted the Latin row to produce its Arabic, scoring that against the same table would grade a lookup against itself. So we score only frames where the Arabic was genuinely detected, which we can identify because every Arabic string we return is tagged as read or derived. That subset (46 frames, median 99 px) skews to better images than the set overall, so compare the two rows against each other, not against the headline numbers.
The thing nobody tells you: resolution decides almost everything
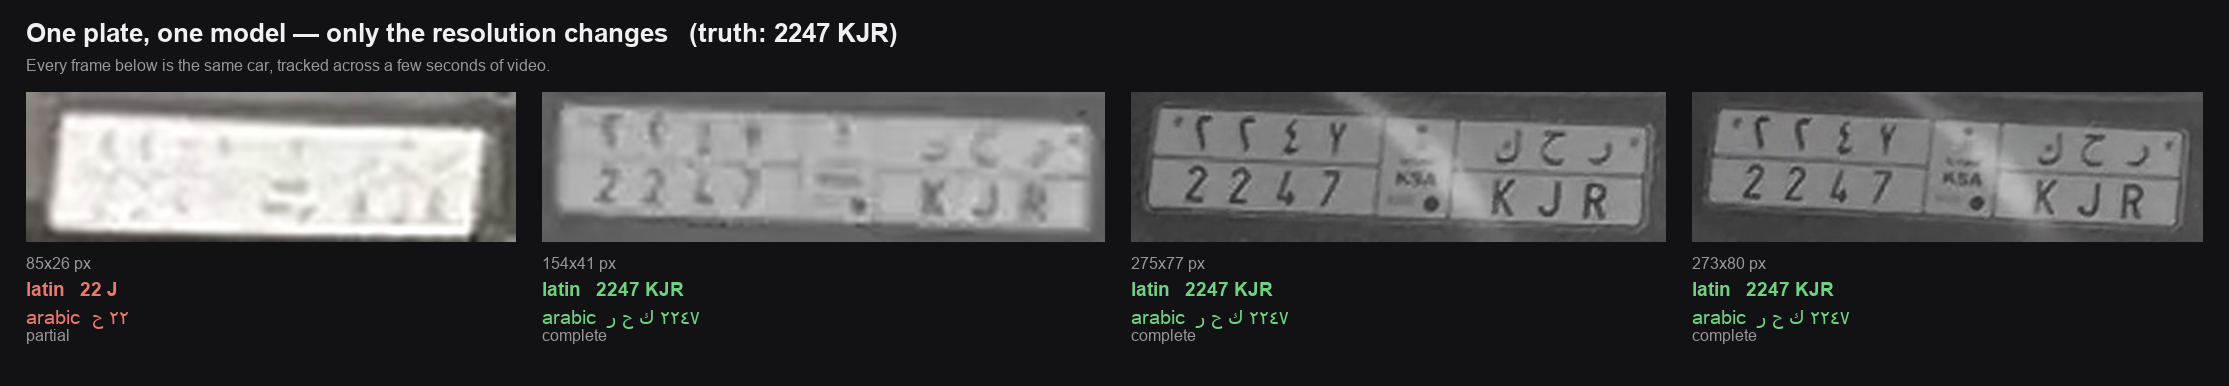
Here is one plate, one model, and nothing changing except how many pixels the camera delivered.
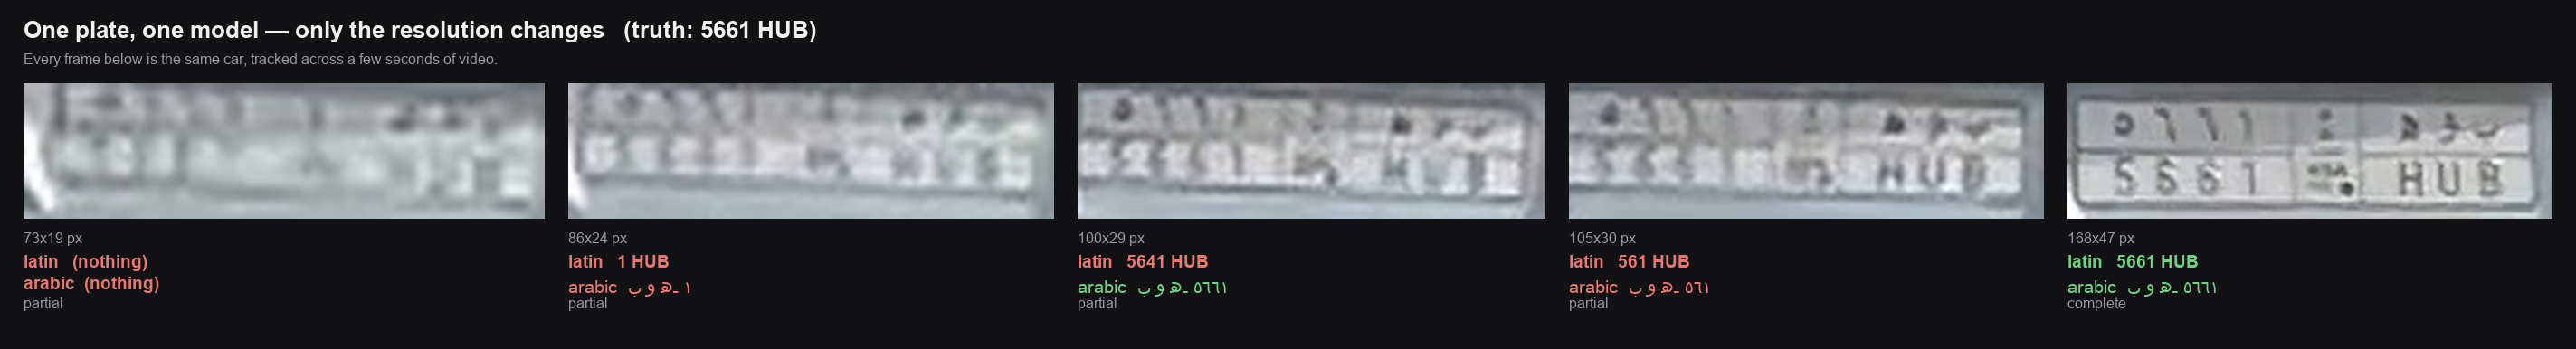
At 73 px wide the system returns nothing. By 86 px it has the letters. By 100 px it has most of the digits. At 168 px it is simply correct. The model is identical in all five frames. The car just got closer.
Break the whole benchmark down the same way:
| plate width | frames | digits | letters (n) | complete plate |
|---|---|---|---|---|
| under 80 px | 48 | 66.7% | 16.7% (36) | 27.1% |
| 80–100 px | 32 | 68.8% | 70.4% (27) | 56.2% |
| 100–150 px | 18 | 77.8% | 100% (18) | 77.8% |
| 150 px and above | 8 | 100% | 100% (8) | 8 of 8 |
Letters are scored only on plates whose registration includes letters — 89 of the 106; the other 17 are digits-only, which is why the letters column has its own denominator. That also explains two rows that otherwise look wrong: complete-plate (27.1%) exceeds letters (16.7%) in the top bucket because the digits-only plates count toward complete-plate and not toward letters; and 100% letters at 100–150 px sits alongside 77.8% complete because the digits, not the letters, are what fail there. Both of the bottom two rows rest on small n — treat them as "no failures observed," not as rates.
Complete-plate accuracy runs 27% → 56% → 78% → 100% as the plate gets wider. Letters collapse hardest at low resolution — 16.7% under 80 px — which is what drags the whole-plate figure down, and it is exactly what you would expect, since a letter carries more shape detail than a digit.
Two caveats we would rather state than have you find. Eight frames cannot establish "100%," and those eight cover only three distinct vehicles, so treat the top row as no failures observed rather than a rate. What the 106 frames across four buckets do establish is a clean monotonic relationship between plate width and accuracy, with no reversal anywhere and no errors at all above 150 px.
This is why our test set is deliberately punishing. Three quarters of it sits under 100 px wide; 92% is under 150 px. These are crops from general-purpose video at distance — not from a camera positioned for plate capture. A 1080p camera specified for ANPR puts 150–300 pixels across a plate as a matter of routine. That is what the specification is for.
So both things are true, and we would rather publish both: our whole-set single-frame number is 50% complete-plate, and it is dominated by images no ANPR installer would accept. If you are specifying a deployment, plate width at the capture point will move your accuracy more than any vendor's model will.
What we do differently
We tell you when the two rows disagree
Reading both scripts gives you a cross-check that converting one row into the other cannot produce. A converted string is derived from the Latin read, so it agrees with it by construction — it can never contradict it, which means it can never warn you. Two independent readings can. Across a larger sample of Saudi plates ours disagree on 11% — meaning at least one is wrong — and on 1.5% the Arabic row is the only readable one.
The Latin row does carry the higher confidence more often, but confidence is not correctness: on any individual plate, a higher score on one row tells you nothing reliable about which is right. So we don't silently pick a winner. We surface the disagreement.
For ANPR the expensive failure is the silent one — a wrong plate means the wrong vehicle is billed or flagged and nobody finds out. A single-script reader returns an answer on that 11% with no indication anything is amiss. A flagged disagreement means a retry, an escalation, or a human, all of which are cheap by comparison.
Arabic you can trust, or know not to
Every Arabic string we return is tagged detected, mixed, or transliterated, so you always know whether you are looking at characters read off the plate or converted from the Latin row. Vendors who convert silently give you no way to tell the difference.
It degrades to incomplete, not to fiction
Worth knowing if you are billing or enforcing on these reads: we checked what the system does on plates that are genuinely marginal.
Separately from the 106 scored frames, our reviewer set aside 8 crops they could not read. On re-examination at least one of those turned out to be legible — the same plate is clear in a neighbouring video frame — which is precisely why these 8 are excluded from every accuracy number on this page. Their ground truth is not reliable enough to score against. They are reported here only as a check on behaviour, which does not depend on knowing the right answer.
On those 8 the system returned nothing on 5 and a partial string on 3 — 29, 32, UU. Every character it returned was one actually present on the plate; the 29 is the correct leading digits of that plate legible in the adjacent frame.
None of the 8 produced a plate-shaped string unrelated to what was on the glass. That is the failure mode that matters: a system which invents a plausible registration for an illegible image bills the wrong vehicle and gives you no way to know. Returning less, or returning nothing, is recoverable — you retry, escalate, or send it to a human.
Per-character confidence you can gate on
Every character we detect comes back with its own confidence score and bounding box, not a single aggregate for the whole plate. If one digit is weak you can see which one and decide what to do about it. We never attach a confidence to a character we did not actually detect — a transliterated glyph has no reading behind it, so inventing a score for it would misrepresent a guess as evidence.
Country-correct handling across all six GCC states
Plate letter conventions genuinely differ between countries — Oman's H is Saudi Arabia's J, Oman's M is Saudi Arabia's Z — and Qatari, Kuwaiti and Bahraini plates carry no Arabic letters to convert at all. We apply the correct convention per country rather than one table everywhere.
How we know these numbers are real
Three commitments, which we would encourage you to demand of any vendor:
The test set was verified unseen, not assumed unseen. Every one of the 106 frames was content-hashed against our entire training corpus before scoring, with zero matches asserted before a single number was produced. Filenames prove nothing — a duplicate image under a different name is still a duplicate.
Ground truth is human, and scoring is end-to-end. A person read each plate. We score the assembled plate string our API actually returns to a customer, not an internal model score. Internal metrics can improve while the customer-facing output gets worse; that is precisely why we stopped treating them as a release gate.
A candidate that doesn't beat the incumbent doesn't ship. Before any retrained model is considered, we score the model currently in production on the same held-out data. Without that comparison there is no threshold that can say "this failed" — only numbers that look plausible in isolation.
That is not hypothetical. We have rejected a candidate whose best checkpoint scored below the model it started from — every training signal looked healthy throughout. It did not ship, because the comparison exists.
It is why we are comfortable publishing the 50%.
Three questions to ask any plate-recognition vendor
Including us. Each is answerable in a sentence by a team that measures, and evasive for a team that doesn't.
1. At what plate resolution is that accuracy figure? Accuracy without a plate-width distribution is not a number. Ours, complete-plate: 27% below 80 px, 56% at 80–100, 78% at 100–150, and no errors above 150 px. Ask for the buckets, not the average.
2. What is your ground truth, and had the model seen it? "Held out" is a claim. Ours: 106 frames covering 42 distinct vehicles, read by a human, content-hashed against the full training corpus with zero matches asserted before scoring.
3. What happened to the last candidate ML model that didn't ship? A team that has never rejected a model has never had a gate. Ours rejected one whose best checkpoint scored below the model it started from — caught because we score the incumbent on the same held-out data before training begins.
If a vendor answers the first without the second and third, you have learned something useful about how they evaluate.
Run it on your own plates
Everything above is our footage and our reviewer. You should not have to take that on faith.
Try it now. Drop a plate image into the demo below and you get back what the API returns — both script rows, per-character confidence, and whether the two rows agree. It also reports the plate width in your image and which resolution bucket it falls into, so you can read the result against the table above instead of guessing whether a poor read was the model or the pixels. That distinction is the whole point of this post, and it is easier to see on your own footage than on ours.
Try It Now
Pick what you want to detect, then upload an image or choose a sample. No signup required.
What do you want to try?
Read just the license plate number - the fastest option.
Upload an image
Tap to take or choose a photo
Drag and drop an image here, or
browse filesJPEG, PNG or WebP - up to 10MB
Result
Upload an image and the result appears here
Or try a sample car:
No account needed, 10 images a day per IP. If you want to run a real sample rather than spot-check, sign up and the first 100 credits are free — same API, same response, no card.
Then run a real volume. The $50 Business plan includes 10,000 credits a month — at one credit per plate processed, enough to put the system against a live camera feed for a while rather than a folder of samples, which is the only way to find out how your own plate-width distribution behaves.
Or send us the footage and we'll do the work. Email [email protected] with up to 200 frames from your cameras and whatever ground truth you have — even a partial list of plates you already know. We will run exactly the benchmark in this post against them and send back the full breakdown: complete-plate and per-script accuracy, the resolution buckets, the frames where the two rows disagreed, and every read we got wrong with the image attached. Turnaround is a few days, there is no cost, and you keep the results whether or not you buy anything.
If the answer comes back worse than the numbers above, you will see exactly why. On our own benchmark, plate width explained more of the variation than anything else we measured — 27% at the bottom of the range against no errors at the top. Expect the resolution column to be the first place worth looking on yours.
If the data cannot leave your building. For enforcement, government and parking operators in the GCC, plate data is frequently subject to residency rules that make a hosted API a non-starter regardless of how well it reads. We license the full pipeline for on-premise installation on your own servers, with no per-read limits — the same models, the same API, running inside your network with nothing leaving it. If that is your constraint, say so in the first email and we will skip straight to it.
ANPR.software builds licence-plate recognition for Gulf plate formats — six countries, bilingual Saudi plates, per-country Arabic conventions, native Arabic character reading, and per-character confidence you can gate on.